Prioritize AI Data Privacy in Australia: Regulator Aligned Controls
20 min readOmniPulse
Data privacy for AI means controlling personal and sensitive information across the full AI lifecycle, from the data you feed into training and prompts through to the outputs, logs and backups a system leaves behind. Organisations must map those data flows before deployment; individuals must assume every prompt could be stored. The OAIC, the EDPB, and firms like Omnipulse now treat this as a lifecycle problem, not a one-off compliance checkbox.
TL;DR:
Most privacy risks in AI stem from misunderstandings of key terms like memorisation, inference, and provenance, not from legal violations.
Data collection and deployment stages pose the highest risks for personal data exposure, especially through untracked sources, biased training, or poorly scoped RAG systems.
Regular testing for re-identification, membership inference, and data drift is essential post-deployment to prevent increasing privacy harms over time.
Contracts with AI vendors must include clear, enforceable guarantees on prompt deletion, data reuse opt-outs, and breach notification timelines; verify claims with audits.
Effective privacy management requires mapping actual data flows, prioritizing exposure points, and implementing technical controls like encryption, retention limits, and privacy-enhancing technologies early.
Table of Contents
-
Data privacy for AI: terms and the lifecycle you need to know
-
The privacy risks that show up at each stage of the AI lifecycle
-
Getting privacy right without slowing AI adoption to a crawl
Data privacy for AI: terms and the lifecycle you need to know
Most privacy failures in AI systems trace back to a term someone misunderstood, not a law someone broke. Getting the vocabulary right matters as much as getting the controls right.
Training is the process of feeding a model large volumes of data so it learns patterns. Fine-tuning adjusts a pre-trained model on a smaller, often more sensitive dataset, such as a company’s customer records. Inference is what happens when the model actually generates a response to a prompt in production. RAG, or retrieval-augmented generation, pulls live data from a knowledge base at inference time and blends it into the answer, which means sensitive documents can surface in outputs even if they were never used in training.
Prompts are what a user types in; outputs are what the model returns; logs record both, often with metadata like timestamps, user IDs and device details attached. Memorisation describes a model reproducing exact or near-exact fragments of its training data. Membership inference is an attack technique that tries to determine whether a specific person’s record was part of a training dataset at all, which matters even when no raw data leaks. Anonymisation aims to make re-identification impossible; de-identification only removes obvious identifiers and often falls short of that standard, a distinction the EDPB has spelled out in detail.
The lifecycle map that regulators care about runs roughly like this:
-
Design — deciding what problem the AI system solves and what data it will need
-
Data collection — sourcing, scraping or licensing datasets, including any personal information embedded in them
-
Training and fine-tuning — where memorisation risk and biased data selection get baked in
-
Deployment and inference — where prompts, RAG lookups and outputs create real-time exposure
-
Monitoring and feedback — where user corrections, logs and retraining loops accumulate new data
-
Decommissioning — where old models, datasets and backups need proper deletion, not just disconnection
Regulators focus their heaviest obligations on collection and deployment, because that’s where personal information most often changes hands without a person’s knowledge.
The privacy risks that show up at each stage of the AI lifecycle
Every stage of an AI system’s life introduces a different kind of exposure, and treating them as one generic “AI risk” is how teams miss the ones that actually bite.
Collection and provenance risks come first. Datasets scraped from the web frequently contain personal details never meant for public reuse, and sensitive fields (health notes, financial records, identity numbers) can sit buried inside otherwise innocuous-looking training sets. Without documented provenance, nobody can later prove what a model was trained on or whether it should be there at all.
Training risks follow. A model can memorise verbatim snippets of sensitive text and reproduce them for an unrelated user. It can also make individuals identifiable through membership inference even when the training data was supposedly de-identified. Biased training data compounds this by baking discriminatory patterns into every downstream decision the model makes. Stanford HAI’s research on foundation models points out that these risks scale with model size and training corpus breadth, meaning the biggest, most capable models often carry the widest exposure.
Inference and output risks hit closest to the end user. A model can regurgitate a fragment of someone else’s data in response to a completely different prompt. RAG systems are particularly exposed here: because they retrieve live documents at answer time, a poorly scoped knowledge base can leak an internal file, a client’s contract terms or a colleague’s performance review straight into a chat response.
Operational risks sit in the plumbing most teams forget to inspect. Prompt logs, feedback stores, backups and cross-tenant infrastructure all accumulate personal data quietly, often past the point anyone remembers it’s there. A multi-tenant AI platform with weak isolation can let one customer’s queries bleed into another’s context window, a failure mode the EDPB’s LLM guidance flags explicitly as a lifecycle risk requiring dedicated mitigation.
Adversarial threats round out the picture. Prompt injection tricks a model into ignoring its instructions and leaking data it was told to protect. Model inversion attacks work backwards from outputs to reconstruct training inputs. Data poisoning corrupts a training set deliberately, so the model learns the wrong lesson on purpose.
Here’s how those risks map against the stage where they typically originate:
-
Collection — scraped personal data, missing consent, undocumented sensitive fields
-
Training — memorisation, re-identification, biased or skewed datasets
-
Fine-tuning — reintroducing sensitive customer data into a general-purpose model
-
Inference — regurgitation, hallucinated but plausible personal details, RAG leakage
-
Feedback loops — retraining on user corrections without re-running privacy checks
-
Storage and backups — retained logs and snapshots outstripping their original purpose
-
Adversarial exposure — injection, inversion and poisoning attacks at any stage above
The Australian Cyber Security Centre’s AI data security guidance recommends provenance tracking, encryption and integrity checks as baseline defences against several of these threats simultaneously, because a dataset with verified lineage is far easier to audit after something goes wrong.
What regulators actually expect from AI data privacy
Regulatory guidance on AI has matured fast, and the expectations are now specific enough to act on rather than just aspire to.
The OAIC’s guidance on commercially available AI products makes clear that the Australian Privacy Principles apply fully to AI use, including tools bought off the shelf from a vendor. Two obligations catch organisations out repeatedly. First, APP 3 governs collection, and the OAIC treats inferred or AI-generated information (a risk score, a predicted preference, a summarised profile) as a collection in its own right, not a mere by-product. Second, APP 10 requires that personal information be accurate and up to date, which means a hallucinated or outdated AI-generated attribute about a real person can itself be a compliance failure, independent of how the underlying model was trained.
The EDPB’s guidance on large language models takes a lifecycle view that Australian organisations dealing with EU data (or simply borrowing best practice) should read closely. It recommends a model-specific risk methodology that sits alongside, not instead of, a formal impact assessment, because a technically secure model can still process personal data unlawfully if the training or RAG pipeline feeding it wasn’t properly scoped. The EDPB is also blunt about anonymisation: claiming a dataset is anonymous without testing it against realistic re-identification attacks isn’t a defensible position anymore.
On the standards side, the NIST AI Risk Management Framework gives organisations a structured way to categorise, measure and manage AI risk, including privacy harms, using a common vocabulary that auditors and regulators increasingly expect to see referenced. ISO/IEC 22989 standardises AI terminology itself, which sounds dry until you’re trying to write a data processing agreement with a vendor and need both parties to mean the same thing by “training data.” Together with Cyber.gov.au’s operational guidance, these frameworks give Australian organisations a defensible reference point when a regulator asks how a decision was made.
A privacy impact assessment (PIA) becomes necessary whenever an AI system will process personal information, particularly before deployment. The OAIC’s 10-step PIA process covers:
-
Mapping every information flow the system touches, from ingestion to output
-
Identifying which APPs or equivalent obligations apply to each flow
-
Assessing risks and their likely impact on individuals
-
Documenting mitigations and assigning someone accountable for each one
-
Reviewing the assessment again before any material change to the system
Skipping this step is the single most common reason AI projects stall midway through legal review, usually because nobody can answer a basic question about where the data actually goes.
Privacy-by-design controls you can put in place now
Privacy-by-design isn’t a philosophy, it’s a build order. Get these decisions right before a model touches production data, and most downstream problems never happen.
Start with purpose limitation. Document exactly why you need each dataset before you collect it, not after a lawyer asks. A narrower dataset is easier to secure, easier to de-identify credibly and far easier to explain to a regulator than a sprawling one collected “just in case.”
De-identification needs testing, not assumptions. Stripping names and emails from a dataset feels like anonymisation but usually isn’t. The EDPB’s own guidance on anonymisation and web scraping insists that a dataset can only be called anonymous after it survives realistic linkage and membership-inference tests, and that the methodology behind that testing needs to be documented and reproducible. Skipping this step is how “anonymous” datasets end up re-identified within weeks of release.
Layer in the standard technical controls, and don’t treat any one of them as sufficient alone:
-
Encryption at rest and in transit for training data, prompts and logs
-
Least-privilege access so only the people who need a dataset can reach it
-
Multi-factor authentication on every system touching personal information
-
Tenant segregation in any multi-customer AI deployment
-
Retention limits with automatic, verifiable deletion, not just archival
Retention deserves its own line of thinking. Prompts, outputs and logs tend to accumulate indefinitely by default because nobody set an expiry date. Decide up front how long each category needs to be kept, tie that decision to a documented legal or operational reason, and build deletion into the system rather than relying on someone remembering to do it manually.
Privacy-enhancing technologies (PETs) are worth evaluating for higher-risk use cases. Differential privacy adds carefully calibrated statistical noise to a dataset or model output so no single individual’s record can be isolated, at the cost of some accuracy. Federated learning trains a model across decentralised devices or servers without ever centralising the raw data, which reduces exposure but adds real engineering complexity and doesn’t eliminate every privacy risk on its own. Neither is a silver bullet; both are genuine trade-offs between privacy strength and system performance.
Document everything with model cards, data cards and a software bill of materials. A model card records what a model was trained on, its known limitations and its intended use. A data card does the same for a dataset: source, collection method, known biases, consent basis. These aren’t paperwork for its own sake, they’re what an auditor, a new team member or a regulator will ask for first when something goes wrong.
Pro Tip: Run your de-identification tests against your own dataset before a vendor or auditor does it for you. Finding a re-identification path internally costs you a afternoon; finding out about it during a regulatory review costs considerably more.
Checking an AI vendor before you sign the contract
Most AI privacy failures aren’t caused by the model itself, they’re caused by a vendor relationship nobody scrutinised properly before go-live.
Start with the operational questions a sales deck won’t answer unprompted. Where does the vendor source its training data, and can they document it? Who are their subprocessors, and where are they located? Who inside the vendor’s organisation has admin access to your data, and how is that access logged? How long do backups persist after you delete something on your end?
Then move to the data lifecycle specifics that determine your actual exposure:
-
Prompt retention — does the vendor store prompts and outputs, and for how long?
-
Reuse for retraining — will your data ever be used to improve the vendor’s general-purpose model, and can you opt out?
-
Deletion timelines — when you request deletion, how long does it actually take to propagate across production systems and backups?
-
Breach notification commitments — what timeframe and detail level does the contract guarantee if something goes wrong?
Get the answers in writing, then get them into the contract itself. The OAIC’s guidance on generative AI development is direct on this point: verifying a vendor’s claim matters more than accepting it, and that verification needs contractual teeth. Push for audit rights, explicit deletion guarantees with defined timeframes, clear limits on how your data can be used, and indemnities that actually cover a privacy breach rather than excluding it in the fine print.
Before rolling a new AI vendor out across the business, run a low-risk pilot using synthetic or already-public data. Test whether the deletion timeline they promised actually holds, whether prompts show up anywhere they shouldn’t, and whether their support team can answer the questions you asked in due diligence without escalating three times. A vendor that can’t demonstrate its own claims in a controlled pilot won’t magically become more transparent once you’re locked into a live contract.
Keeping AI systems privacy-safe after they go live
Privacy work doesn’t end at deployment, it just changes shape. The systems that stay compliant are the ones with a routine, not just a launch checklist.
Logging and monitoring need a retention period tied to actual need, not default settings. Keep enough log history to investigate an incident properly, but not so much that you’re accumulating a second, unmanaged copy of sensitive data alongside your primary systems.
Periodic testing matters as much as initial testing. Re-identification and membership-inference risks aren’t static, they shift as a model gets fine-tuned further or as new data joins a RAG knowledge base. Build re-identification testing into a recurring schedule rather than a one-off pre-launch exercise, and monitor for data drift that might be quietly changing what the model exposes.
Incident response needs an AI-specific playbook. A model exfiltration event or a prompt-injection leak doesn’t look like a typical data breach, and generic incident response plans often miss the specific containment steps an AI system needs, such as rotating API keys, disabling a compromised RAG source, or rolling back to a prior model version. Backup and restoration strategies should be tested against this scenario specifically, not assumed to work because they worked for a database outage once.
Governance needs named owners, not shared responsibility. Assign a privacy owner accountable for the PIA and its mitigations, a data owner responsible for the datasets themselves, a security lead for technical controls, and where relevant a data protection officer coordinating across all three. Set a recurring cadence, quarterly is common, where these roles review what’s changed in the system and whether the original risk assessment still holds.
-
Log inputs and outputs with a retention period matched to genuine need
-
Schedule recurring re-identification and membership-inference testing
-
Build an AI-specific incident response playbook before you need one
-
Assign named, accountable roles rather than diffuse responsibility
What individuals should do before typing into an AI tool
The rules for individuals are simpler than the compliance frameworks above, but they get ignored just as often, usually because a chat interface feels private when it isn’t.
Treat every prompt, upload or conversation as potentially stored or reused unless a provider’s terms say clearly otherwise. Research from Stanford HAI is blunt on this point: never enter passwords, identity documents, health information or trade secrets into an AI service you haven’t vetted, no matter how routine the task feels.
For sensitive work, prefer an enterprise or private deployment over a free consumer tool, and actually check the provider’s settings for data-use opt-outs rather than assuming defaults protect you. Where you’re testing a prompt or sharing an example publicly, use redacted or synthetic data instead of a real customer record or your own personal details.
-
Never paste passwords, ID numbers, health data or client information into an unvetted AI tool
-
Check whether the provider offers an opt-out from having your prompts used for training
-
Use synthetic or redacted examples when demonstrating or testing a prompt
-
Know that under the Australian Privacy Principles, you can generally request access to, or correction of, personal information an organisation holds about you, including AI-derived profiles
Pro Tip: Before using a new AI tool for anything work-related, search its provider’s privacy policy for the word “retain.” If you can’t find a clear answer on how long your prompts are kept, assume the answer is indefinitely.
Where the ethics get harder than the law
Compliance and ethics diverge more often in AI than in most other areas of data handling, and that gap is where most of the genuinely hard decisions live.
A system can satisfy every applicable privacy law and still make a call that feels wrong to the people affected by it. Training a model on publicly scraped content is often legally defensible in a given jurisdiction, yet the people whose forum posts, photos or reviews ended up in that dataset were never asked and likely never imagined their words would train a commercial product. Consent, in the traditional privacy sense of a person actively agreeing, barely applies to most large-scale AI training data.
Fairness questions compound this. A model trained on historical data will often reproduce the biases embedded in that history, whether that’s lending decisions, hiring patterns or medical diagnoses skewed toward whichever population was overrepresented in the training set. Fixing this after the fact is far harder than preventing it at the data collection stage, which is exactly why ethical review needs to happen before training starts, not after a model is already generating biased outputs in production.
Transparency is the third pressure point. Individuals increasingly have no practical way to know an AI system processed their data at all, let alone which one, when, or for what purpose. Model cards and data cards help close that gap for organisations willing to publish them, but voluntary transparency only works when enough of the industry adopts it. Ethics in this space isn’t a separate checklist from compliance, it’s the set of questions compliance alone doesn’t force anyone to ask.
Why anonymisation keeps failing in practice
Anonymisation sounds like a solved problem. It isn’t, and AI has made the gap between “de-identified” and “genuinely anonymous” wider, not narrower.
The core issue is that AI models are exceptionally good at finding patterns humans wouldn’t spot, which is precisely what makes re-identification attacks effective against datasets that would have been safe a decade ago. Removing a name and date of birth used to be enough. Now, a combination of postcode, purchase history and a handful of behavioural signals can re-identify a person even when every obvious identifier has been stripped out.
Membership inference attacks add another layer of difficulty. Even when a dataset never gets exposed directly, an attacker with query access to a trained model can sometimes determine whether a specific individual’s data was used in training at all, which is itself a privacy harm the traditional definition of “anonymised” doesn’t account for.
The EDPB’s guidance on anonymisation draws a hard line here: a dataset can only be treated as anonymous once it has been tested against realistic attack scenarios and that testing has been documented in a way that can be reproduced and audited later. Many organisations skip this step entirely, relying on a generic de-identification checklist that was never validated against the specific dataset, model or attacker capability at hand.
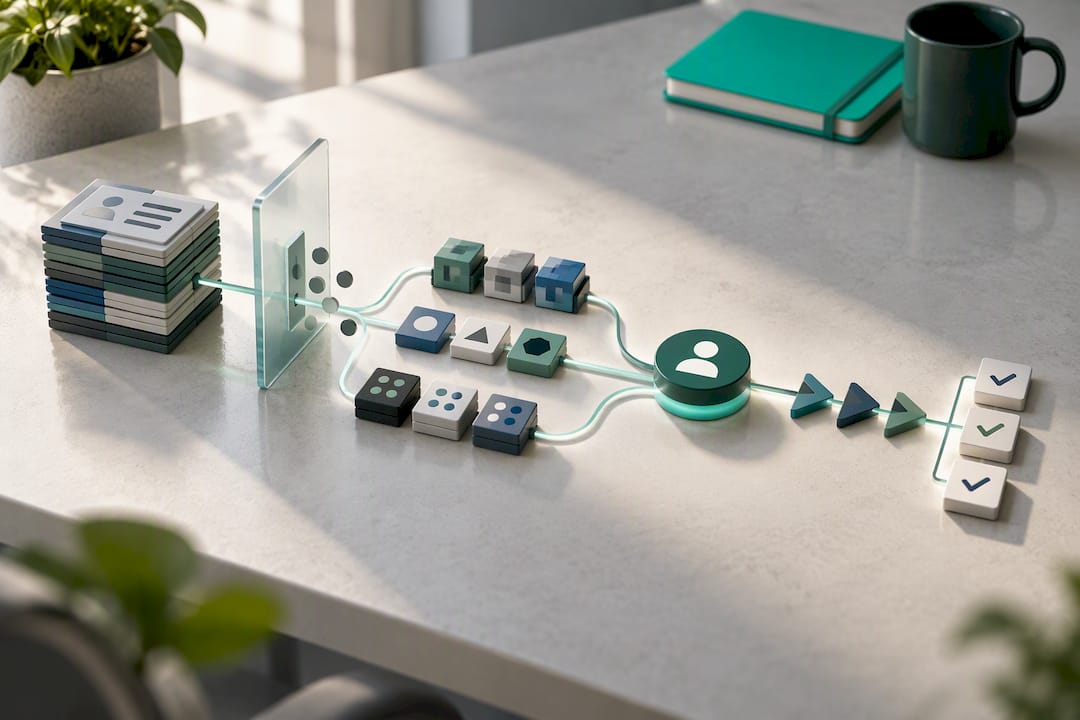
The practical takeaway is that anonymisation is a claim you have to prove, repeatedly, not a status you apply once and forget. As models get more capable at pattern recognition, the bar for what counts as genuinely anonymous keeps rising with them.
What rights you actually have over your AI-processed data
Most people assume AI sits outside normal privacy law. It doesn’t, and the rights that apply to a spreadsheet of customer records apply just as much to a model trained on that same data.
Under the Australian Privacy Principles, individuals generally have the right to request access to personal information an organisation holds about them, including information an AI system has inferred or generated, not just data that was manually entered somewhere. The OAIC’s guidance is explicit that inferred attributes count as collected personal information, which means a person can, in principle, ask what a system inferred about them and how accurate it is.
The right to correction follows the same logic. If an AI system has generated an inaccurate profile, a hallucinated attribute or an outdated prediction about a real person, APP 10’s accuracy requirement gives that person grounds to request a correction, even though the “record” in question was generated by a model rather than typed by a human.
Erasure is where things get genuinely complicated. Deleting a person’s record from a database is straightforward; removing their influence from a model that has already been trained on their data is not, and in many cases isn’t technically possible without retraining the model from scratch. This is exactly why minimising what goes into training in the first place matters more for AI than it did for traditional databases: you can’t always take it back out cleanly once it’s baked in.
What the guidance gets wrong about priority
The conventional advice on AI privacy treats every control as equally urgent: encrypt everything, minimise everything, document everything, test everything. That’s not wrong, but it’s not useful either, because most organisations don’t have the resources to do all of it at once, and treating a retention policy gap as equally urgent to an unvetted RAG knowledge base is how the wrong fires get put out first.
The gap that catches out even well-resourced teams isn’t a missing encryption key, it’s a dataset nobody catalogued, a prompt-retention setting nobody checked, or a vendor contract with no deletion guarantee at all. These sit in blind spots precisely because they don’t look dangerous day to day. A diagnostic-first approach, mapping actual data flows and vendor exposure before writing a single policy, tends to surface these faster than a generic best-practice checklist ever will, because it starts from what the organisation is actually doing rather than what a template assumes it’s doing.
Prioritise by exposure, not by how easy a control is to implement. Fix the vendor contract with no audit rights before you polish an already-encrypted internal database. Test your riskiest dataset for re-identification before you write a model card for a low-stakes internal tool. Sequencing, more than coverage, is what separates organisations that actually reduce risk from ones that just generate paperwork.
Brodie S
Getting privacy right without slowing AI adoption to a crawl
Most mid-sized businesses don’t need another generic AI policy template, they need someone to look at their actual systems and tell them where the real exposure sits. Omnipulses strategy engagement is built around a Business Diagnostic Process that maps your data flows, vendor relationships and AI use cases against real privacy and revenue risk, then prioritises fixes by what actually matters, not by what’s easiest to write up.
Such an engagement is typically priced with a one-off fee and delivers a prioritised roadmap to teams or boards indicating which datasets need attention first, which vendor contracts need renegotiating, and where AI adoption can safely accelerate because the groundwork is already sound. Some providers back this with a guarantee: if the diagnostic doesn’t uncover enough opportunity to justify the engagement, the work continues at no extra cost until it does.
If your organisation is using AI tools without a clear picture of where personal data actually flows, book a 30-minute AI readiness session and find out what a proper diagnostic would surface before a regulator or a customer does it for you.
Where to go for the primary guidance
The OAIC’s guidance on commercially available AI products is the starting point for understanding how the Australian Privacy Principles apply to AI tools, including inferred data and accuracy obligations.
The EDPB’s LLM guidance covers lifecycle risks specific to large language models, from training through to RAG and feedback loops, plus its companion guidance on anonymisation and web scraping.
For operational and security controls, the Australian Cyber Security Centre’s AI data security guidance sets out provenance tracking, encryption and classification measures alongside the broader NIST AI Risk Management Framework.
Stanford HAI’s brief on foundation models and privacy is worth reading for the systemic view of how model scale changes privacy risk, separate from any single organisation’s compliance position.
This article is general information, not a substitute for advice from a qualified lawyer. Consult a qualified legal professional about your own circumstances before acting on anything here.
Sources
-
Guidance on privacy and the use of commercially available AI products | OAIC
-
AI Privacy Risks & Mitigations Large Language Models (LLMs) | EDPB
FAQ
Does AI keep your data private?
Not automatically. Whether your data stays private depends on the specific provider’s settings, retention policy and whether they reuse prompts for retraining, so check the terms rather than assuming privacy by default. Providers built for enterprise use generally offer stronger guarantees than free consumer tools.
What is data privacy in artificial intelligence?
Data privacy for AI means controlling personal and sensitive information across the full AI lifecycle, from the data used in training through to prompts, outputs, logs and backups. It requires both legal compliance, such as meeting Australian Privacy Principle obligations under OAIC guidance, and technical controls like encryption and access limits.
What is the 30% rule in AI?
If you’ve seen this term used elsewhere, it likely refers to a specific vendor’s internal metric rather than a recognised industry standard, so treat it with caution until you can verify its source.
How will AI affect data privacy?
AI expands what counts as personal information, since inferred and AI-generated attributes can trigger the same obligations as directly collected data under the OAIC’s guidance. It also introduces new risks, like memorisation and membership inference, that traditional data protection frameworks weren’t originally built to address, which is why regulators keep issuing AI-specific guidance rather than relying on older rules alone.